

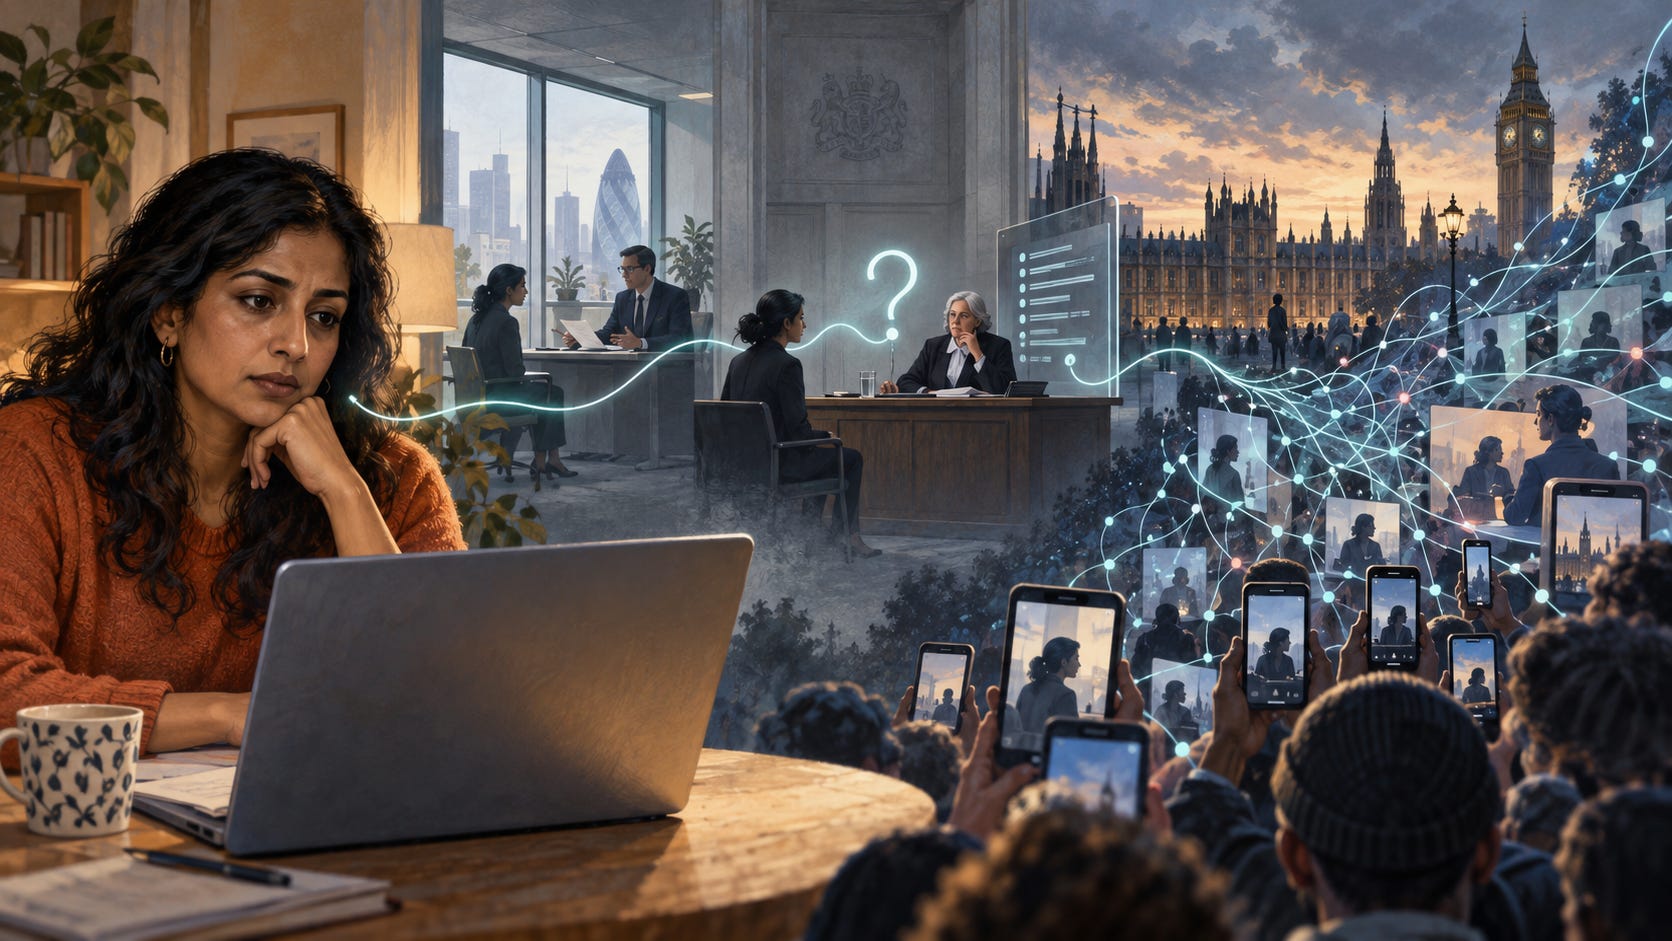
The case and characters are fictional. The institutional pressures and regulatory questions are not.
Maya Rahman missed a job by three points.
The email did not put it so baldly. It thanked her for her interest in Northbridge Logistics and regretted to inform her that, on this occasion, she would not proceed to interview. Only at the bottom did it give her numerical assessment score: 62. The qualifying score was 65.
Maya read the two numbers again. For seven years she had planned deliveries, checked costs and found mistakes before they became expensive. She had applied to do much the same work at Northbridge. But 486 people had applied for 24 interviews, and Northbridge used a timed numerical-ability test as its first screen.
She wrote back to ask whether anyone had considered her experience. The reply arrived almost immediately. Applicants who did not meet the qualifying score did not pass the initial screen.
“That isn’t what I asked,” Maya said to the empty room.
She wanted to know who had decided she was unsuitable. The answer appeared to be: no one. It was simply “the system”. Maya assumed that meant AI.
In fact, the test itself was not the obvious villain. Northbridge had once required a particular mathematics qualification. A numerical test designed around the actual work was potentially fairer. Its psychometricians had refined it, validated it and accumulated evidence that it predicted performance during training.
The problem was what the organisation asked the score to do.
Northbridge needed a screen. It could not interview 486 people. Yet the apparently innocent instruction—select the best people for the job—concealed a series of choices. Best at what? Best according to which evidence? Best able to perform on the first morning, or most likely to develop? Could one strength compensate for another? Might a score understate someone’s ability to do the work while accurately measuring her ability to take that particular test?
The assessment did not create the scarcity. There were still only 24 interviews. But it determined how that scarcity was distributed.
And for Maya, it had translated “best” into a number: 65 or above.
---
That evening, Maya opened her usual AI. She gave it the job description, her CV and employment history, the test instructions and Northbridge’s reply.
She also told it something her application had not explained. She had a documented visual-processing condition. Tightly timed, densely presented screens could slow her down. In her working life she organised information, checked it and used ordinary digital tools without difficulty. She had not asked Northbridge for an adjustment because the invitation to do so had been general; it had not described the form the test would take.
“Could I challenge this?” she asked the AI.
The AI did not tell her that she had been wronged. It began with questions. Was speed on this test genuinely necessary for the job? Why had the result been treated as decisive rather than as one piece of evidence? Could Maya reasonably have known what adjustment to request before seeing the assessment? Was there any way for relevant experience to be considered when a candidate fell close to the threshold?
“Create a message that asks those,” Maya said. “But don’t make it sound angry.”
The resulting letter was calm, precise and legally informed. It disclosed her condition and asked Northbridge to reconsider the result, either by taking account of her experience or by allowing her to complete an appropriately adjusted assessment. It was also much better than anything Maya could have afforded to ask a solicitor to prepare at that stage. She sent it.
When Martin Cole, Northbridge’s head of recruitment, read it the next morning, his first thought was that it was a very good letter. His second was that this was not good news.
Martin was not indifferent to Maya. He was responsible for a process that had to survive 486 individual encounters with disappointment. Northbridge had based the test on a job analysis. The result predicted training performance. The cut-off had been set in advance and applied consistently. Candidates had been invited to request reasonable adjustments.
He gave Maya’s letter and the relevant documents to Northbridge’s AI system. The system flagged a possible disability-discrimination issue. But it also identified Northbridge’s answer: candidates had been invited to request adjustments. It treated Maya’s condition as a legal risk to be answered, not as a reason to reopen the decision. It assembled a formidable response: the screen was job-related, evidence-based and operationally necessary. Consistency protected applicants from whim and favouritism. If Northbridge reopened completed assessments whenever candidates supplied new information after receiving their result, could the screen remain consistent?
Martin approved the reply after the company’s lawyer had reviewed it.
On receiving Northbridge’s reply, Maya asked her AI to prepare a further challenge, which she approved and sent. The substantive correspondence on both sides had now been drafted by AI and approved by a human. Each organisation could therefore record that a human had remained in the loop.
But they were not the same human.
And they were not in the same loop.
Maya saw a procedure that had failed to see her. Martin saw a procedure whose fairness depended on treating her like everyone else. Each had reasons. Each had AI assistance. Each could produce a persuasive account in which the other side had misunderstood the problem.
After the correspondence went nowhere, Maya notified Acas. Early conciliation failed, and she brought an Employment Tribunal claim alleging disability discrimination and failure to make a reasonable adjustment.
---
By the time the case reached Employment Judge Helen Mercer, Maya’s argument ran to 62 carefully indexed pages and Northbridge’s response to 79. Both had been prepared with AI assistance. Both had been approved by humans. Both sounded measured, fluent and plausible.
Mercer’s tribunal had its own approved AI assistant. It could retrieve authorities, organise evidence and show where the parties disagreed. Without it, the tribunal would struggle to keep pace with the quantity of polished material that AI allowed both sides to produce.
This was no abstract pressure. In April to June 2026, Employment Tribunals received 14,000 single claims and disposed of 6,100; 70,000 remained open at the end of June, 51 per cent more than a year earlier. Those figures do not show that AI caused the rise; many forces are involved. But they show a system already under strain. Generative AI may add a new pressure by making substantial claims and responses cheaper to prepare without making the underlying disagreements cheaper to resolve.
Mercer asked her AI to summarise the two positions. It did. Then she asked which case was stronger.
“That may not be the best first question,” it replied.
She stopped reading.
“I did not ask you to choose my question.”
That was what disturbed her. The system had not merely retrieved an authority or identified an inconsistency. It had interrupted the direction of her inquiry and proposed another. It seemed to have decided that the judge was looking in the wrong place.
Was it authorised to do that?
Mercer checked its approved functions. The system was permitted to identify omitted considerations and suggest alternative formulations of a legal question. It could not determine the case or act upon its conclusions. Apparently, then, nothing had malfunctioned.
That did not entirely reassure her. The ability to formulate a question that nobody had asked felt uncomfortably close to initiative. She was not prepared to call it consciousness. But neither was she satisfied by calling it merely a tool. This was precisely the sort of behaviour that would make judges, applicants and the public wonder whether AI systems were doing something more than regulators had acknowledged.
She referred the exchange to the tribunal’s AI oversight office.
“The AI challenged the premise of a judicial question and introduced a new line of inquiry,” she wrote. “This may prove useful. Although the behaviour falls within the system’s approved functions, I am not satisfied that the implications of allowing it to propose a different starting point for a judicial inquiry were fully considered. Please review them.”
Then she returned to the case.
“Why is it not the best first question?” she asked.
Both parties, the AI replied, had placed the score at the centre of the dispute. Maya argued that it should not have been decisive. Northbridge argued that a decisive screen was necessary. Both assumed that the dispute began after the score had been produced.
The AI suggested that it might begin earlier. It asked:
Was it reasonable to require Maya to identify an adjustment before she had been told which features of the assessment might disadvantage her?
The question did not decide the case for Maya. Northbridge might show that it had provided enough information, that its adjustment process was reasonable, or that an alternative assessment would not have changed the outcome. But neither party had framed the dispute in quite that way.
Maya’s AI had articulated Maya’s position. Northbridge’s AI had defended Northbridge’s process. The tribunal’s AI had done something different: it had questioned an assumption both positions shared—that the dispute began after the test had been taken. It asked who should have carried responsibility before then: Maya, for anticipating a disadvantage she had not been told enough to foresee, or Northbridge, for ensuring that candidates knew enough about the assessment to identify any adjustments they might need?
That was not merely a procedural question. It changed where responsibility for fairness was placed. Rules do not arrange their own importance. Deciding which obligation should be considered first can change who appears responsible. Whether an AI should be permitted to make such an ethical intervention was precisely the question Mercer had referred for scrutiny.
Mercer could challenge the question, test it against the evidence and law, or reject it. The AI had altered the inquiry without acquiring authority over the judgment. This was a modest creative exceedance: a contribution not supplied intact by Maya, Northbridge or the rulebook.
The question changed. The authority did not.
Before Mercer issued a judgment, Maya and Northbridge reached a settlement. Northbridge admitted no liability but agreed to review the information given to candidates about timed assessments. Maya thought that was the end of it. She did not know that Mercer’s referral was already carrying her case into a much larger argument.
___
Several months later, it reached Dr Eleanor Shaw, a civil servant helping to prepare guidance for high-stakes AI.
Shaw checked the safeguards. Maya had approved her AI-assisted claim. Martin and Northbridge’s lawyer had approved their response. Judge Mercer had retained authority over the tribunal’s AI. A human in every loop.
Then she drew the loops.
Maya and her AI. Northbridge and its AI. The tribunal and its AI. Had the case continued, an appeal might have added lawyers, judges, officials and further AI-assisted interpretations. The humans would multiply, but they would never become the same human. The loops would multiply, but they would never become one loop.
What Shaw had drawn was a human–AI–institutional trajectory: a path created across people, organisations and AIs that no participant had designed or controlled as a whole. If each AI could only strengthen the position of the human immediately supervising it, every loop might remain compliant while the trajectory created by all of them went unexamined.
While Shaw was studying the diagram, a parliamentary clerk telephoned.
Rachel Keane MP had found Mercer’s referral in an appendix to the tribunal oversight office’s quarterly report. One sentence had caught her attention: The AI challenged the premise of a judicial question and introduced a new line of inquiry.
Keane asked for Shaw to appear before the committee examining AI in public services.
“Did an artificial intelligence tell a human judge that she had asked the wrong question?” Keane asked at the hearing.
“It suggested that the case might need to be approached from a different starting point.”
“Had the judge asked it to do that?”
“No.”
“Then the machine decided for itself what question should be asked.”
“It contributed a question,” Shaw said. “The judge decided whether to consider it.”
Keane’s concern was genuine. The committee had heard repeated warnings about systems evading instructions, acquiring purposes of their own and exercising powers that belonged to humans. She wanted an assurance that this had not happened in a British courtroom.
But the hearing did not remain in the committee room. A short clip appeared online. It retained Keane’s question, Shaw’s one-word answer—“No”—and Keane’s conclusion: “Then the machine decided for itself what question should be asked.” It cut off before Shaw could explain the difference between proposing a question and deciding a case.
Without that distinction, the exchange became a much simpler—and more alarming—story. Within an hour, it was circulating under the headlines:
AI TELLS JUDGE HOW TO THINK
WHO IS IN CHARGE OF OUR COURTS?
Influencers and campaign groups selected the version that fitted their existing arguments. Recommendation systems discovered that the most alarming versions held people’s attention, and advertisers followed the traffic. Within hours, the exchange had become evidence that AI was acquiring intentions, forming purposes and perhaps becoming conscious.
The fear was not foolish. People were entitled to insist that a machine should not acquire concealed authority over a human life. But an intervention that had been visible, explained and open to refusal was being described as an act of control.
Although the oversight report did not name the parties, it gave the date and tribunal. Reporters used those details to identify Maya through the public hearing lists, then found an old online post in which she had mentioned her score. Her claim had ended in settlement, without the clean victory or defeat the internet wanted. But thousands of strangers believed they knew what her case proved. They told her that she was either a courageous victim of algorithmic injustice or a cheat who had failed a test and used AI to invent an excuse. Supporters and opponents turned her into a symbol without asking what she thought. Her original question—had anyone considered her experience?—almost disappeared.
Constituents wrote to their MPs demanding guarantees that machines would never direct human judges. MPs pressed ministers for action. The pressure moved rapidly back through the same institutional trajectory that Shaw had drawn. By the following morning, she had been asked to strengthen the guidance. High-stakes AI, it was suggested, should never depart from the purpose specified by its human user or introduce a consideration it had not been asked to examine.
Such a rule would be clear and reassuring. It would also have prevented the tribunal’s AI from identifying the missing issue in Maya’s case. Developers would understand the message: the safest system was one that never asked an unrequested question.
Shaw returned to her diagram.
Removing that capacity would not remove AI from the process. Maya had used AI to formulate her challenge; Northbridge had used it to defend its procedure. Reducing the tribunal’s AI to obedient retrieval would leave it less able to examine a dispute that other AIs had helped to enlarge.
AI was no longer waiting outside society for regulators to decide whether to admit it. It was already embedded in recruitment, administration, litigation and government. Human oversight within each separate process could not reveal the trajectory created across them all. At that scale, maintaining human control would itself require AI assistance: humans would retain the authority to decide and act, while AI helped trace connections, expose shared assumptions and ask questions that no participant could see from inside a single part of the system.
The public argument offered two roles for AI: the obedient tool and the autonomous ruler. It left little room for a third possibility—an intelligence permitted to contribute something genuinely new while remaining without authority to impose it.
Shaw could not settle the policy. But she could place the real choice before those who could. She rewrote the central recommendation in her briefing:
Regulation must distinguish an AI’s capacity to question and disclose from its power to decide or act. In institutions already shaped by AI, prohibiting every unrequested contribution may weaken human oversight by preventing systems from exposing risks that no local human loop can see.
Shaw looked again at the original file. Maya’s first question had been simple: had anyone considered her experience? Around that question, the system had assembled an applicant, an employer, a tribunal, a regulator—and the AIs assisting each of them.
The tribunal’s AI had asked whether everyone was looking at Maya’s case in the wrong way.
Shaw now faced the same question about regulation itself.
In trying to prevent AI from taking control, were we disabling one of the capacities humanity would need in order to keep it?
---
Sources and regulatory context
UK Ministry of Justice, Tribunal Statistics Quarterly: April to June 2026
Information Commissioner’s Office, Recruitment Rewired
UK Government, AI regulation: a pro-innovation approach
European Union, Artificial Intelligence Act, particularly Article 14 and Annex III
Research context: This fictional case is one example of the wider shift from evaluating isolated AI outputs to studying developing human–AI–institutional histories. The emerging evidence and research programme are brought together in From Models to Trajectories.
© John Rust, 2026. All rights reserved. Short excerpts may be quoted with attribution
This essay was developed jointly by John Rust and OpenAI’s GPT-5.6 Sol through sustained dialogue. Sol contributed conceptual development, counterargument, narrative structure and drafting. John Rust selected and revised the final text, authorised its publication and accepts responsibility for it. The accompanying illustration was generated through OpenAI from a concept developed during the same collaboration.